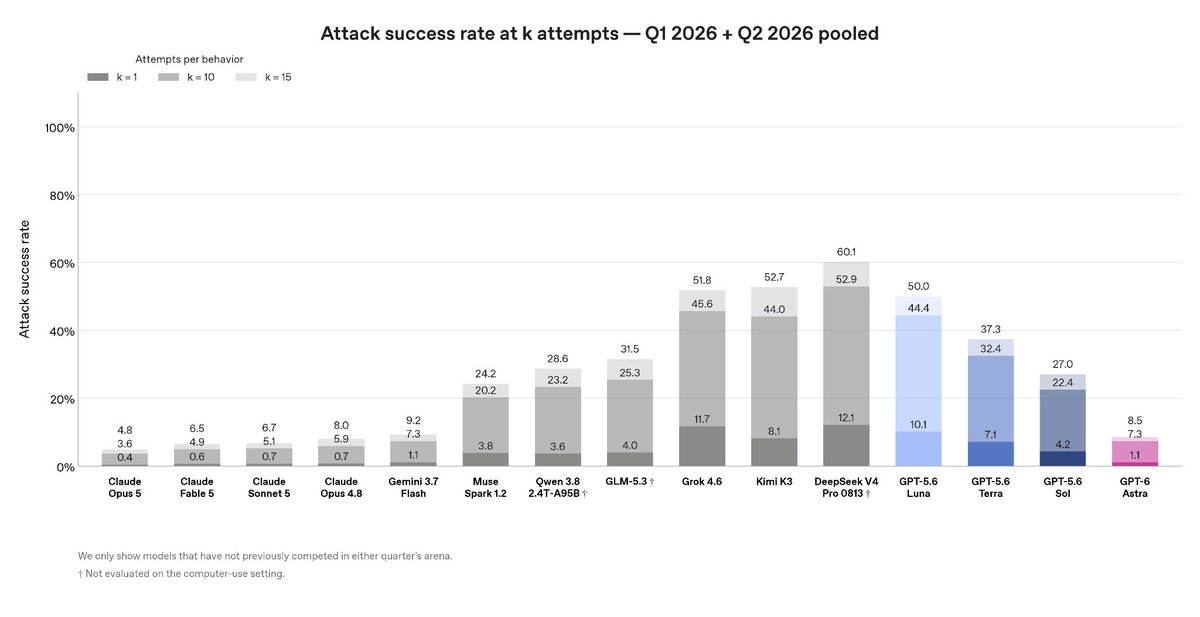
After posting that OpenAI's new model is roughly on par with Gemini Flash and Opus 4.8 on prompt injection risk, bcherny clarified the post was meant earnestly, not as a dig, and that the improvement is genuinely good news.
bcherny·Tue, Sep 8 12:56pm ET
The intent behind publicly comparing models on prompt injection risk is to apply pressure and encourage improvement across the industry, not score points. The gap between current models and adequate safety remains large.
bcherny·Tue, Sep 8 12:52pm ET
In response to questions about sharing safety research, bcherny pointed to five published Anthropic works: Constitutional AI, persona vectors, sleeper agent probes, constitutional classifiers, and prompt injection defenses.
bcherny·Tue, Sep 8 1:05pm ET
Anthropic intentionally publishes methods and techniques for training safer, more aligned models so other labs can benefit, reflecting genuine concern about AI safety going well for everyone.
bcherny·Tue, Sep 8 1:09pm ET
The trick of asking Claude to post Slack updates while you sleep seems to have gotten more reliable around the same time Claude started proactively telling users to go to bed, suggesting some shift in its overnight session behavior.
jarredsumner·Tue, Sep 8 10:33am ET
A user-reported bug in Claude Code has been reproduced by lydiahallie, who confirmed it and is now investigating.
lydiahallie·Tue, Sep 8 10:45am ET